How to Scrape Reddit: Data API, JSON Endpoints or HTML Scraping
Reddit data is best collected through the official Reddit Data API: it returns posts, comments and subreddit information as clean JSON, it is free for low-volume non-commercial use within a per-minute limit, and since late 2025 new applications go through an approval review. Appending .json to a Reddit URL and parsing HTML pages are the other two options people use, but both are more fragile, more tightly throttled and harder to square with Reddit's terms, so treat them as fallbacks for small, one-off samples.
Competing tutorials usually hand over a script and stop there. This guide compares the three routes side by side, explains the rules and limits that changed after 2023, shows a read-only API example that does not involve signing in to any account, and describes where proxies fit when you sample public pages at a careful pace.
Rotating proxies for public data
Rotating proxies to spread small samples of public pages across addresses at a polite pace
Three Ways to Get Reddit Data
| Criterion | Data API (OAuth) | JSON endpoints | HTML scraping |
|---|---|---|---|
| Format | Structured JSON | Structured JSON | Markup that changes |
| Access | Registered app, approval for new apps | No registration | No registration |
| Rate limit | Published per-minute limit per app | Much lower, applied per IP | Throttled per IP, challenge pages |
| Stability | High, versioned | Medium, can be restricted at any time | Low, layouts change |
| Terms | Covered by the Data API Terms | Grey zone, still Reddit's content rules | Restricted by the User Agreement |
| Good for | Research, monitoring, moderation tools | Quick look at a few threads | Almost nothing the first two cannot do |
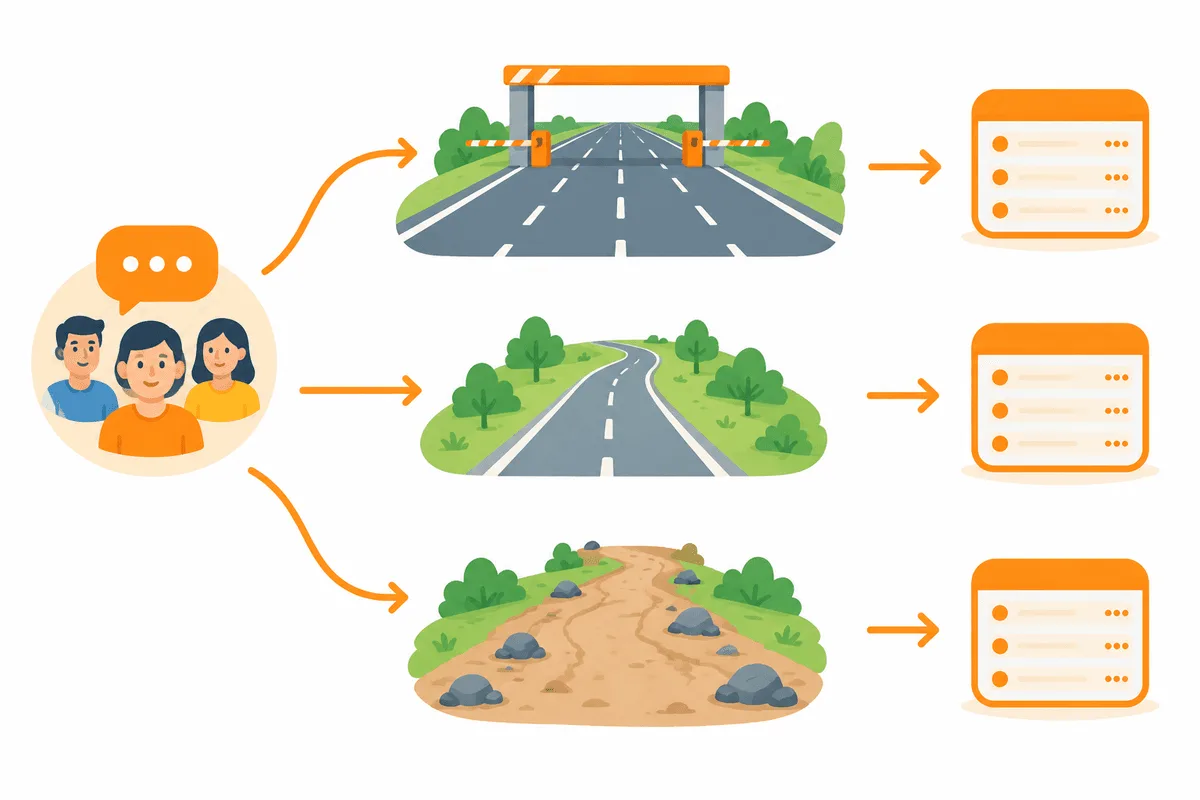
The ranking is clear: the API first, JSON endpoints for a quick peek, HTML only when a page has no other source.
What Changed: Reddit's Data Policy After 2023
In 2023 Reddit moved its API to paid access for large-scale and commercial users, while keeping a free tier for smaller, non-commercial projects. The free tier is commonly described as 100 requests per minute per OAuth client, averaged over a ten-minute window, with a much lower limit for unauthenticated calls. Commercial use, including training AI models on Reddit content, requires a separate agreement with Reddit.
Two more developments matter for anyone collecting data:
- App approval. Reports from late 2025 describe a new review step: developers now apply for API access and explain their use case before receiving credentials. Plan for a waiting period.
- Enforcement. Reddit restricted crawlers in its robots.txt in 2024 and has taken companies it accused of large-scale scraping to court. Collecting Reddit content at scale outside the API is a real legal risk, not a theoretical one.
Exact numbers and procedures change, so read the current Data API Terms, Developer Terms and the r/redditdev announcements before you start.
Route 1: The Official Data API
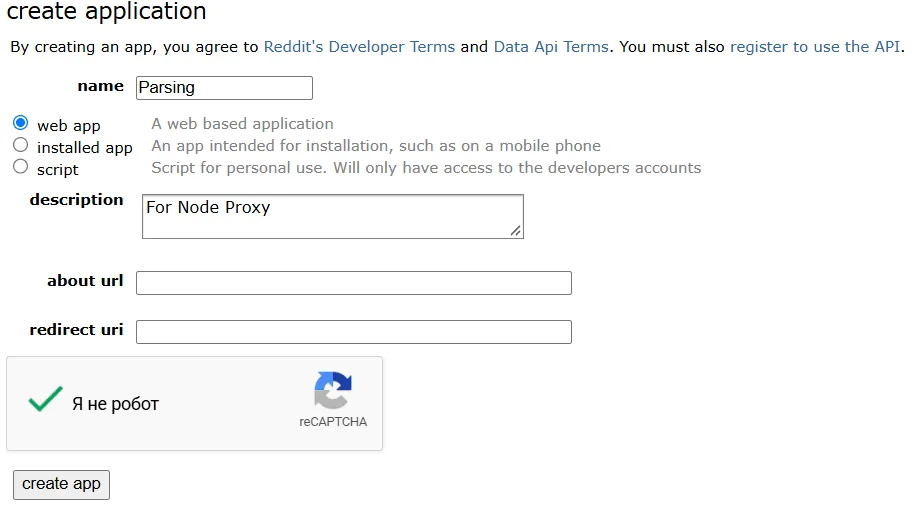
Step 1. Register an App
Sign in to your own Reddit account in a normal browser, open the apps page in your preferences, and create a script-type app. You will receive a client ID and a client secret. Fill in the description honestly: what you collect and why.
Step 2. Read Public Data in Read-Only Mode
PRAW, the Python Reddit API Wrapper, handles authentication and respects the rate-limit headers for you. With only the client ID and secret, it works in read-only mode, so the script never signs in as a user.
import os, praw

reddit = praw.Reddit(
    client_id=os.environ["RD_APP_ID"],
    client_secret=os.environ["RD_APP_SECRET"],
    user_agent="python:topic-monitor:v0.3 (by u/your_research_account)",
)

rows = []
for post in reddit.subreddit("homeautomation").top(time_filter="week", limit=50):
    rows.append({
        "id": post.id,
        "title": post.title,
        "score": post.score,
        "comments": post.num_comments,
        "created": post.created_utc,
        "link": f"https://www.reddit.com{post.permalink}",
    })
print(len(rows), rows[0]["title"])
Notes on the code:
- The User-Agent should be unique and descriptive, in the platform, app name, version and contact format that Reddit asks for. Generic or browser-imitating agents are throttled.
- Keep the app credentials in environment variables.
- Store post IDs rather than usernames when the analysis does not need them.
Step 3. Respect the Limits
Each API response includes headers that report how many requests remain and when the window resets. PRAW waits automatically; if you call the API directly, read those headers and sleep when the remaining count gets low. Comments of large threads are loaded in batches, so a single thread with thousands of comments can cost many requests.
Route 2: JSON Endpoints
Adding .json to most Reddit listing or thread URLs returns the same data the site uses. It is convenient for a quick look:
import httpx, time

ua = {"User-Agent": "python:thread-sample:v0.1 (by u/your_research_account)"}
link = "https://www.reddit.com/r/homeautomation/top.json?t=week&limit=25"
reply = httpx.get(link, headers=ua, timeout=30, follow_redirects=True)
if reply.status_code == 429:
    time.sleep(120)            # back off and try much later, or stop for the day
else:
    for child in reply.json()["data"]["children"]:
        print(child["data"]["score"], child["data"]["title"])
Limits for unauthenticated JSON requests are far below the API's and are applied per IP address. Reddit can also restrict or close this access without notice, so do not build a product on it. For anything recurring, move to the API.
Route 3: HTML Pages and Where Proxies Fit
Scraping HTML pages of Reddit makes sense only for the rare piece of public information that is not in the API or JSON, and only in small volumes. Reddit's User Agreement restricts automated collection without permission, so stay at research-sample scale and check the terms first.
If you do sample public pages, the per-IP limits are the practical constraint. A pool of rotating proxies spreads a small number of requests across addresses so that one IP does not hit the ceiling, which is a matter of politeness rather than speed. The rules that keep such sampling acceptable:
- Only logged-out, public pages. No signing in, no private or quarantined communities, no automation of any account.
- One request every few seconds per address, with random pauses, and no parallel bursts.
- Stop immediately on 429 responses, challenge pages or a block notice. Do not solve captchas or try to get around them.
- Collect the fields you need and nothing else.
For managing real brand accounts on Reddit rather than collecting data, see our separate guide on Reddit proxies. More general advice on proxies in web scraping explains rotation, sessions and pool sizing.
Personal Data and Ethics
Reddit posts are public, but they are still written by people, and usernames combined with post history can identify someone. Under GDPR, and under Russia's 152-FZ when it applies, collecting and storing such data needs a legal basis and safeguards.
- Collect for a defined purpose and keep only the fields required for it.
- Pseudonymise usernames in research datasets, or drop them.
- Respect deletions: if a post is removed on Reddit, remove it from your copy when you refresh data.
- Do not republish full threads or profiles of individual users.
Our overview of collecting data from social networks compares how these rules play out on other platforms.
Common Errors
| Error | Meaning | What to do |
|---|---|---|
| 401 Unauthorized | Wrong app credentials or expired token | Check the ID and secret, request a new token |
| 403 Forbidden | Private, banned or quarantined community, or blocked client | Skip the community, review your User-Agent |
| 429 Too Many Requests | Rate limit hit | Wait for the window to reset, slow down |
| Empty listings | Wrong sort or time filter | Check t and limit parameters |
Reddit Scraping FAQ
Is it legal to scrape Reddit?
Using the official Data API within its terms is the safest way to collect Reddit data. Scraping pages outside the API is restricted by Reddit's User Agreement, and Reddit has taken large-scale scrapers to court, so keep any page sampling small and non-commercial and follow personal-data law.
Is the Reddit API free?
There is a free tier for non-commercial and low-volume use, commonly cited as 100 requests per minute per app. Commercial use and large volumes require a paid agreement with Reddit, and new apps now go through an approval process.
Do I need to log in to collect Reddit data?
No. A registered app can read public posts and comments in read-only mode with its own credentials. Automating sign-in to a Reddit user account for collection is not needed and goes against the rules.
What does adding .json to a Reddit URL do?
It returns the page data in JSON format, which is handy for a quick look at a few threads. The limits are low, applied per IP, and the access can be restricted at any time, so it is not suitable for regular collection.
Do I need proxies to scrape Reddit?
Not for the official API, which is limited per app rather than per address. Proxies help only when you sample public pages, spreading a small number of requests so that a single IP is not throttled.
How do I avoid 429 errors on Reddit?
Read the rate-limit headers, pause when the remaining quota is low and use a descriptive User-Agent. If you still get 429, wait for the window to reset rather than adding more parallel requests.